
Data Sources & Strategy#
Why This Pipeline Exists#
RavenPack is the gold standard for firm-level financial news data: every headline is pre-tagged with entity identifiers, relevance scores, sentiment, and topic classifications. But its terms of use prohibit uploading headline text to LLMs like ChatGPT for NLP analysis.
The workaround: source headlines independently from free sources, then fuzzy-match them to RavenPack to inherit its entity metadata. Only the independently-sourced headlines get uploaded to LLMs — RavenPack’s text stays local, but its metadata travels via the crosswalk.
Three headline sources in this pipeline:
RavenPack — the metadata reference. High-quality entity tags and sentiment, but headlines cannot be uploaded to LLMs.
GDELT — free, massive, but noisy. Covers the open web, not wire services. Only ~7% of its headlines match RavenPack per-headline, but its enormous volume makes it the largest contributor to overall RavenPack coverage.
Scraped newswires (PR Newswire, Business Wire, GlobeNewswire) — higher per-headline match rates (same wire services RavenPack draws from), but smaller total volume limits their coverage contribution.
Both GDELT and newswire crosswalks are combined to maximize RavenPack coverage. The pipeline links each free headline to its best RavenPack match, transferring entity IDs and sentiment without violating terms of use.
import re
from pathlib import Path

import matplotlib.dates as mdates
import matplotlib.pyplot as plt
import polars as pl

from settings import config

DATA_DIR = Path(config("DATA_DIR"))
Key Result: RavenPack Headline Coverage#
_cw = pl.read_parquet(DATA_DIR / "newswire_ravenpack_crosswalk.parquet")

from pull_free_newswires import load_newswire_headlines as _load_nw

_nw_total_urls = (
    _load_nw()
    .with_columns(pl.col("date").cast(pl.Date))
    .filter(
        (pl.col("date") >= _cw["date"].min()) & (pl.col("date") <= _cw["date"].max())
    )
    .select(pl.col("source_url").n_unique())
    .collect()
    .item()
)
_nw_matched_urls = _cw["nw_source_url"].n_unique()
_nw_match_rate = _nw_matched_urls / _nw_total_urls * 100

_rp_full = (
    pl.scan_parquet(DATA_DIR / "ravenpack_djpr.parquet")
    .with_columns(pl.col("timestamp_utc").cast(pl.Date).alias("date"))
    .filter(
        (pl.col("date") >= _cw["date"].min()) & (pl.col("date") <= _cw["date"].max())
    )
    .select("rp_story_id")
)
_rp_total_stories = _rp_full.select(pl.col("rp_story_id").n_unique()).collect().item()
_rp_matched_stories = _cw["rp_story_id"].n_unique()
_rp_match_rate = _rp_matched_stories / _rp_total_stories * 100

pl.DataFrame(
    {
        "metric": [
            "RP headlines matched",
            "NW headlines matched",
            "Crosswalk pairs",
            "Date range",
        ],
        "value": [
            f"{_rp_match_rate:.1f}% ({_rp_matched_stories:,} / {_rp_total_stories:,})",
            f"{_nw_match_rate:.1f}% ({_nw_matched_urls:,} / {_nw_total_urls:,})",
            f"{len(_cw):,}",
            f"{_cw['date'].min()} to {_cw['date'].max()} ({_cw['date'].n_unique():,} dates)",
        ],
    }
)
/opt/homebrew/Caskroom/mambaforge/base/lib/python3.10/site-packages/google/api_core/_python_version_support.py:275: FutureWarning: You are using a Python version (3.10.14) which Google will stop supporting in new releases of google.api_core once it reaches its end of life (2026-10-04). Please upgrade to the latest Python version, or at least Python 3.11, to continue receiving updates for google.api_core past that date.
  warnings.warn(message, FutureWarning)
| metric | value |
|---|---|
| str | str |
| "RP headlines matched" | "5.0% (843,900 / 16,806,654)" |
| "NW headlines matched" | "24.9% (894,391 / 3,590,391)" |
| "Crosswalk pairs" | "895,043" |
| "Date range" | "2010-12-01 to 2026-02-28 (4,10… |
1. RavenPack — ravenpack_djpr.parquet#
Source script: pull_ravenpack.py
One row per news article / entity event from the RavenPack Dow Jones Press
Release feed. Filtered for US companies (country_code='US'),
high relevance (\(\geq 90\)), and single-firm stories only.
RavenPack’s strengths: curated entity matching, sentiment scores, and topic classification. Its content is ~95% wire services (Dow Jones, PR Newswire, Business Wire, GlobeNewswire). The limitation: headline text cannot be uploaded to LLMs under RavenPack’s terms of use.
Key columns:
Column |
Description |
|---|---|
|
Publication timestamp (UTC) |
|
RavenPack entity identifier |
|
Company name |
|
Article headline text |
|
Sentiment score (−1 to +1) |
|
Composite Sentiment Score (0–100) |
|
Entity relevance to the article (0–100) |
|
RavenPack topic classification |
|
News type (e.g. press-release, article) |
|
Name of the news source |
rp = pl.scan_parquet(DATA_DIR / "ravenpack_djpr.parquet")
n_rows = rp.select(pl.len()).collect().item()
cols = rp.collect_schema().names()
print(f"Rows: {n_rows:,}  |  Columns: {len(cols)}")
print(f"Column names: {cols}")
Rows: 40,175,083  |  Columns: 25
Column names: ['timestamp_utc', 'rp_story_id', 'rp_entity_id', 'entity_type', 'entity_name', 'country_code', 'relevance', 'event_sentiment_score', 'event_relevance', 'event_similarity_key', 'event_similarity_days', 'topic', 'rp_group', 'rp_type', 'sub_type', 'property', 'fact_level', 'category', 'news_type', 'rp_source_id', 'source_name', 'provider_id', 'provider_story_id', 'headline', 'css']
Example rows#
rp.head(5).collect()
| timestamp_utc | rp_story_id | rp_entity_id | entity_type | entity_name | country_code | relevance | event_sentiment_score | event_relevance | event_similarity_key | event_similarity_days | topic | rp_group | rp_type | sub_type | property | fact_level | category | news_type | rp_source_id | source_name | provider_id | provider_story_id | headline | css |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| datetime[ns] | str | str | str | str | str | f64 | f64 | f64 | str | f64 | str | str | str | str | str | str | str | str | str | str | str | str | str | f64 |
| 2000-01-01 17:52:28 | "52D513EA9040443376A6B1747B0FA8… | "047E26" | "COMP" | "Sprint Corp." | "US" | 92.0 | null | null | null | null | null | null | null | null | null | null | null | "FULL-ARTICLE" | "B5569E" | "Dow Jones Newswires" | "DJ" | "DN20000101000112" | "Sprint Says No Y2K Rollover Pr… | -0.06 |
| 2000-01-04 16:20:09 | "EBA7EA21C1F4C4E3DAB00078A0158F… | "619882" | "COMP" | "JPMorgan Chase & Co." | "US" | 91.0 | null | null | null | null | null | null | null | null | null | null | null | "TABULAR-MATERIAL" | "B5569E" | "Dow Jones Newswires" | "DJ" | "DN20000104001275" | "Chase Manhattan (CMB) Block: 2… | 0.0 |
| 2000-01-04 17:09:31 | "35BAA12B8E5A3EFF50C5D677F53101… | "619882" | "COMP" | "JPMorgan Chase & Co." | "US" | 90.0 | null | null | null | null | null | null | null | null | null | null | null | "NEWS-FLASH" | "B5569E" | "Dow Jones Newswires" | "DJ" | "DN20000104001590" | "Chase H&Q Starts MotherNature.… | 0.06 |
| 2000-01-04 18:16:36 | "0AA17F1E569B8DEECBD24539957F89… | "619882" | "COMP" | "JPMorgan Chase & Co." | "US" | 92.0 | null | null | null | null | null | null | null | null | null | null | null | "TABULAR-MATERIAL" | "B5569E" | "Dow Jones Newswires" | "DJ" | "DN20000104001889" | "FHLB $200M 2-Yr Taps Via J.P. … | 0.0 |
| 2000-01-04 19:14:26 | "97B979351D2EE5CF60063AA2F780ED… | "619882" | "COMP" | "JPMorgan Chase & Co." | "US" | 91.0 | null | null | null | null | null | null | null | null | null | null | null | "FULL-ARTICLE" | "B5569E" | "Dow Jones Newswires" | "DJ" | "DN20000104002192" | "J. P. Morgan Trade Weighted Ef… | 0.0 |
Date range#
rp.select(
    pl.col("timestamp_utc").min().alias("earliest"),
    pl.col("timestamp_utc").max().alias("latest"),
).collect()
| earliest | latest |
|---|---|
| datetime[ns] | datetime[ns] |
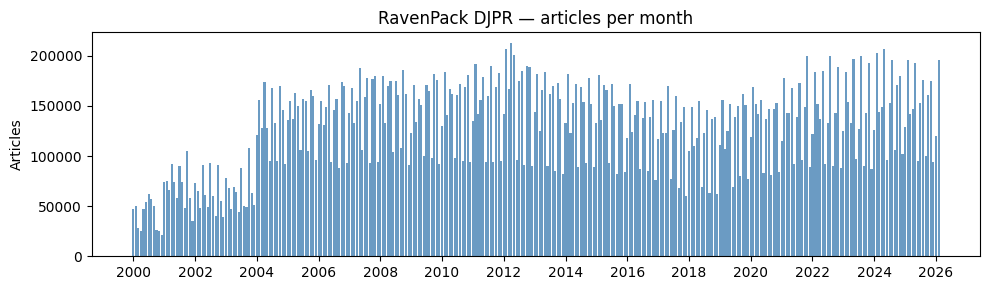
| 2000-01-01 00:24:51 | 2026-02-28 23:19:01.856 |
Articles per month#
rp_monthly = (
    rp.with_columns(pl.col("timestamp_utc").cast(pl.Date).alias("date"))
    .group_by(pl.col("date").dt.truncate("1mo"))
    .agg(pl.len().alias("n_articles"))
    .sort("date")
    .collect()
)

fig, ax = plt.subplots(figsize=(10, 3))
ax.bar(
    rp_monthly["date"].to_list(),
    rp_monthly["n_articles"].to_list(),
    width=25,
    color="steelblue",
    alpha=0.8,
)
ax.xaxis.set_major_locator(mdates.YearLocator(2))
ax.xaxis.set_major_formatter(mdates.DateFormatter("%Y"))
ax.set_ylabel("Articles")
ax.set_title("RavenPack DJPR — articles per month")
fig.tight_layout()
plt.show()
2. S&P 500 Constituents — sp500_constituents.parquet#
Source script: pull_sp500_constituents.py
Historical membership list of the S&P 500 index from CRSP
(crsp_m_indexes.dsp500list_v2). Each row is one membership spell
for a single PERMNO — i.e. the period during which a stock was part
of the index.
Key columns:
Column |
Description |
|---|---|
|
CRSP permanent security identifier |
|
Date the stock entered the S&P 500 (inclusive) |
|
Date the stock exited the S&P 500 (exclusive) |
|
Index identifier |
|
Membership flag |
sp = pl.scan_parquet(DATA_DIR / "sp500_constituents.parquet")
n_rows_sp = sp.select(pl.len()).collect().item()
cols_sp = sp.collect_schema().names()
print(f"Rows: {n_rows_sp:,}  |  Columns: {len(cols_sp)}")
print(f"Column names: {cols_sp}")
Rows: 8,284  |  Columns: 13
Column names: ['permno', 'indno', 'mbrstartdt', 'mbrenddt', 'mbrflg', 'indfam', 'comnam', 'ticker', 'ncusip', 'namedt', 'nameenddt', 'siccd', 'exchcd']
Example rows#
sp.head(5).collect()
| permno | indno | mbrstartdt | mbrenddt | mbrflg | indfam | comnam | ticker | ncusip | namedt | nameenddt | siccd | exchcd |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| i64 | i64 | datetime[ns] | datetime[ns] | str | i64 | str | str | str | datetime[ns] | datetime[ns] | i64 | i64 |
| 10006 | 1000500 | 1957-03-01 00:00:00 | 1984-07-18 00:00:00 | "NORM" | 1100500 | "AMERICAN CAR & FDRY CO" | null | null | 1925-12-31 00:00:00 | 1954-05-31 00:00:00 | 3740 | 1 |
| 10006 | 1000500 | 1957-03-01 00:00:00 | 1984-07-18 00:00:00 | "NORM" | 1100500 | "A C F INDUSTRIES INC" | null | null | 1954-06-01 00:00:00 | 1962-07-01 00:00:00 | 3740 | 1 |
| 10006 | 1000500 | 1957-03-01 00:00:00 | 1984-07-18 00:00:00 | "NORM" | 1100500 | "A C F INDUSTRIES INC" | "ACF" | null | 1962-07-02 00:00:00 | 1968-01-01 00:00:00 | 3743 | 1 |
| 10006 | 1000500 | 1957-03-01 00:00:00 | 1984-07-18 00:00:00 | "NORM" | 1100500 | "A C F INDUSTRIES INC" | "ACF" | "00080010" | 1968-01-02 00:00:00 | 1984-06-28 00:00:00 | 3743 | 1 |
| 10030 | 1000500 | 1957-03-01 00:00:00 | 1969-01-08 00:00:00 | "NORM" | 1100500 | "AMERICAN BRAKE SHOE & FDRY" | null | null | 1925-12-31 00:00:00 | 1943-04-26 00:00:00 | 3310 | 1 |
Membership date range#
sp.select(
    pl.col("mbrstartdt").min().alias("earliest_start"),
    pl.col("mbrstartdt").max().alias("latest_start"),
    pl.col("mbrenddt").min().alias("earliest_end"),
    pl.col("mbrenddt").max().alias("latest_end"),
).collect()
| earliest_start | latest_start | earliest_end | latest_end |
|---|---|---|---|
| datetime[ns] | datetime[ns] | datetime[ns] | datetime[ns] |
| 1925-12-31 00:00:00 | 2026-02-09 00:00:00 | 1928-08-24 00:00:00 | 2026-02-27 00:00:00 |
Unique constituents over full history#
n_unique = sp.select(pl.col("permno").n_unique()).collect().item()
print(f"Distinct PERMNOs that have ever been in the S&P 500: {n_unique:,}")
Distinct PERMNOs that have ever been in the S&P 500: 1,956
3. GDELT Headlines — gdelt_headlines/#
Source script: pull_gdelt_headlines.py
Page-title headlines extracted from GDELT’s Global Knowledge Graph 2.0,
filtered to English articles mentioning at least one organization.
Stored as a Hive-partitioned data lake (year=YYYY/month=MM/data.parquet).
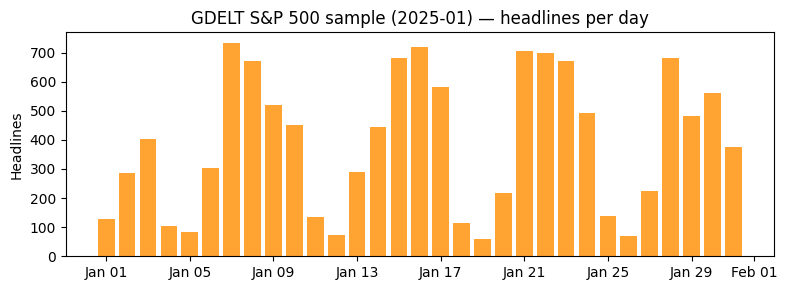
GDELT is free and massive (~400k articles/day), but its content comes from the open web — blogs, aggregators, regional news — not the wire services that dominate RavenPack. This means fuzzy-match overlap with RavenPack is low (~7%). The false-positive problem and filtering quality are explored in notebook 02. We will use GDELT in more depth in a separate project.
Key columns:
Column |
Description |
|---|---|
|
GKG record timestamp |
|
Full URL of the source article |
|
Domain / common name of the news source |
|
Page title extracted from |
|
Semicolon-separated organization mentions |
from pull_gdelt_headlines import (
    SAMPLE_MONTH,
    filter_to_month,
    load_gdelt_headlines,
)

gd = filter_to_month(load_gdelt_headlines(), SAMPLE_MONTH)
n_rows_gd = gd.select(pl.len()).collect().item()
cols_gd = gd.collect_schema().names()
print(f"Rows: {n_rows_gd:,}  |  Columns: {len(cols_gd)}")
print(f"Column names: {cols_gd}")
Rows: 12,109  |  Columns: 6
Column names: ['gkg_date', 'source_url', 'source_name', 'headline', 'year', 'month']
Example rows#
gd.head(5).collect()
| gkg_date | source_url | source_name | headline | year | month |
|---|---|---|---|---|---|
| datetime[μs, UTC] | str | str | str | i64 | i64 |
| 2025-01-17 20:00:00 UTC | "https://www.prnewswire.com/new… | "prnewswire.com" | "Equality Now Welcomes Biden's … | 2025 | 1 |
| 2025-01-29 09:45:00 UTC | "https://www.prnewswire.com/new… | "prnewswire.com" | "Epson Announces New TROY Group… | 2025 | 1 |
| 2025-01-21 17:00:00 UTC | "https://www.prnewswire.com/new… | "prnewswire.com" | "Brigade to bring vehicle safet… | 2025 | 1 |
| 2025-01-16 12:30:00 UTC | "https://www.prnewswire.com/new… | "prnewswire.com" | "Forte Telecom Becomes First to… | 2025 | 1 |
| 2025-01-16 15:30:00 UTC | "https://www.prnewswire.com/new… | "prnewswire.com" | "New Study Finds 73% of Hotelie… | 2025 | 1 |
Date range#
gd.select(
    pl.col("gkg_date").min().alias("earliest"),
    pl.col("gkg_date").max().alias("latest"),
).collect()
| earliest | latest |
|---|---|
| datetime[μs, UTC] | datetime[μs, UTC] |
| 2025-01-01 00:00:00 UTC | 2025-01-31 23:30:00 UTC |
Headlines per day#
gd_collected = gd.collect()
gd_daily = (
    gd_collected.with_columns(pl.col("gkg_date").cast(pl.Date).alias("date"))
    .group_by("date")
    .agg(pl.len().alias("n_headlines"))
    .sort("date")
)

fig, ax = plt.subplots(figsize=(8, 3))
ax.bar(
    gd_daily["date"].to_list(),
    gd_daily["n_headlines"].to_list(),
    color="darkorange",
    alpha=0.8,
)
ax.xaxis.set_major_formatter(mdates.DateFormatter("%b %d"))
ax.set_ylabel("Headlines")
ax.set_title(f"GDELT S&P 500 sample ({SAMPLE_MONTH}) — headlines per day")
fig.tight_layout()
plt.show()
4. Free Newswires — newswire_headlines/#
Source script: pull_free_newswires.py
Press release headlines scraped from PR Newswire via sitemap crawling, then filtered locally to S&P 500 companies using normalized company name substring matching.
These are the same wire services that RavenPack draws from, scraped directly from their public-facing websites. This makes scraped newswires the primary headline source for matching to RavenPack — because the underlying press releases are identical, fuzzy-match rates are much higher than with GDELT.
Key columns:
Column |
Description |
|---|---|
|
Publication date (YYYY-MM-DD) |
|
Press release headline text |
|
Full URL of the press release |
|
Wire service name (PR Newswire) |
|
S&P 500 company name matched via substring |
|
CRSP permanent security identifier |
|
Stock ticker symbol |
from pull_free_newswires import load_newswire_headlines
from pull_sp500_constituents import load_sp500_names_lookup, normalize_company_name

raw = load_newswire_headlines().collect()

# Map Hive partition key to human-readable source name
if "source" in raw.columns and "source_name" not in raw.columns:
    source_map = {"prnewswire": "PR Newswire"}
    raw = raw.with_columns(
        pl.col("source")
        .replace_strict(source_map, default="Unknown")
        .alias("source_name")
    )

# Filter to S&P 500 companies via normalized name matching
lookup = pl.from_pandas(load_sp500_names_lookup())
names = sorted(
    [n for n in lookup["comnam_norm"].unique().to_list() if n], key=len, reverse=True
)
pattern = "(" + "|".join(re.escape(n) for n in names) + ")"

raw = raw.with_columns(
    pl.col("headline")
    .map_elements(normalize_company_name, return_dtype=pl.Utf8)
    .alias("headline_norm")
)
nw = raw.filter(pl.col("headline_norm").str.contains(pattern))
nw = nw.with_columns(
    pl.col("headline_norm").str.extract(pattern, group_index=1).alias("matched_norm")
)
lookup_dedup = lookup.select("comnam_norm", "comnam", "permno", "ticker").unique(
    subset=["comnam_norm"], keep="first"
)
nw = nw.join(
    lookup_dedup, left_on="matched_norm", right_on="comnam_norm", how="left"
).rename({"comnam": "matched_company"})
nw = nw.drop("headline_norm", "matched_norm").lazy()

n_rows_nw = nw.select(pl.len()).collect().item()
cols_nw = nw.collect_schema().names()
print(f"Rows: {n_rows_nw:,}  |  Columns: {len(cols_nw)}")
print(f"Column names: {cols_nw}")
Rows: 1,205,063  |  Columns: 11
Column names: ['headline', 'source_url', 'date', 'source', 'year', 'month', 'day', 'source_name', 'matched_company', 'permno', 'ticker']
Example rows#
nw.head(5).collect()
| headline | source_url | date | source | year | month | day | source_name | matched_company | permno | ticker |
|---|---|---|---|---|---|---|---|---|---|---|
| str | str | str | str | i64 | i64 | i64 | str | str | i64 | str |
| "New York City REIT, Inc. Annou… | "https://www.businesswire.com/n… | "2021-01-01" | "businesswire" | 2021 | 1 | 1 | "Unknown" | "FIRST INTL BANCSHARES INC" | 56805 | "FIBN" |
| "INVESTOR ALERT: Kirby McInerne… | "https://www.businesswire.com/n… | "2021-01-01" | "businesswire" | 2021 | 1 | 1 | "Unknown" | "LIMITED BRANDS INC" | 64282 | "LTD" |
| "Bristol Myers Squibb Provides … | "https://www.businesswire.com/n… | "2021-01-01" | "businesswire" | 2021 | 1 | 1 | "Unknown" | "BRISTOL MYERS SQUIBB CO" | 19393 | "BMY" |
| "COVID-19 Impact and Recovery A… | "https://www.businesswire.com/n… | "2021-01-02" | "businesswire" | 2021 | 1 | 2 | "Unknown" | "INDUSTRIAL BANCORP" | 47159 | "INB" |
| "COVID-19 Impact and Recovery A… | "https://www.businesswire.com/n… | "2021-01-02" | "businesswire" | 2021 | 1 | 2 | "Unknown" | "INTEL CORP" | 59328 | "INTC" |
Full headline examples#
for h in nw.select("headline").head(8).collect()["headline"].to_list():
    print(f"  • {h}")
  • New York City REIT, Inc. Announces Common Stock Dividend for First Quarter 2021
  • INVESTOR ALERT: Kirby McInerney LLP Reminds Investors That a Class Action Lawsuit Has Been Filed Against Restaurant Brands International Inc. and Encourages Investors to Contact the Firm Before February 19, 2021
  • Bristol Myers Squibb Provides Update on Status of Contingent Value Rights
  • COVID-19 Impact and Recovery Analysis | Industrial Gases Market Procurement Intelligence Report Forecasts Spend Growth of over $38 billion
  • COVID-19 Impact and Recovery Analysis | Litigation Services Market Procurement Intelligence Report Forecasts Spend Growth of Over USD 194 Billion | SpendEdge
  • Mining Explosives Market Procurement Intelligence Report With COVID-19 Impact Analysis | Global Forecasts, 2020-2024 | SpendEdge
  • Oil Spill Solutions Market Procurement Intelligence Report With COVID-19 Impact Analysis | Global Forecasts, 2021-2025 | SpendEdge
  • Juniper Research: OTT TV & Video Subscriptions to Reach 2 Billion Globally by 2025, Driven by Services From Traditional Broadcasters
5. Newswire–RavenPack Crosswalk — newswire_ravenpack_crosswalk.parquet#
Source script: create_newswire_ravenpack_crosswalk.py
Fuzzy-matched bridge between free newswire headlines and RavenPack DJ Press
Release headlines. Each row is the single best RavenPack match for a given
newswire headline on the same calendar date, kept only when the
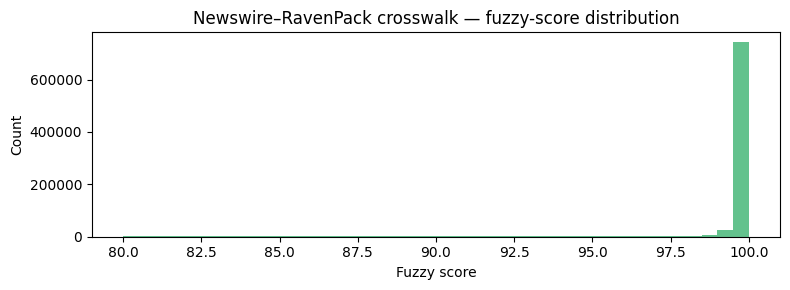
token_sort_ratio score is \(\geq 80\).
This is the key pipeline output. It enables enriching free newswire data with RavenPack’s entity identifiers and sentiment scores, without uploading RavenPack’s headline text to any external service.
Key columns:
Column |
Description |
|---|---|
|
Calendar date of the matched headlines |
|
URL of the newswire press release |
|
Original headline from the newswire source |
|
Wire service identifier (e.g. |
|
RavenPack unique story identifier |
|
RavenPack entity identifier |
|
Company name as recorded by RavenPack |
|
Headline text from RavenPack |
|
News source as classified by RavenPack |
|
Token-sort-ratio similarity score (80–100) |
cw = pl.scan_parquet(DATA_DIR / "newswire_ravenpack_crosswalk.parquet")
n_rows_cw = cw.select(pl.len()).collect().item()
cols_cw = cw.collect_schema().names()
print(f"Rows: {n_rows_cw:,}  |  Columns: {len(cols_cw)}")
print(f"Column names: {cols_cw}")
Rows: 895,043  |  Columns: 10
Column names: ['date', 'nw_source_url', 'nw_headline', 'nw_source', 'rp_story_id', 'rp_entity_id', 'rp_entity_name', 'rp_headline', 'rp_source_name', 'fuzzy_score']
Example rows#
cw.head(5).collect()
| date | nw_source_url | nw_headline | nw_source | rp_story_id | rp_entity_id | rp_entity_name | rp_headline | rp_source_name | fuzzy_score |
|---|---|---|---|---|---|---|---|---|---|
| date | str | str | str | str | str | str | str | str | f64 |
| 2010-12-01 | "https://www.prnewswire.com/new… | "A Festivus For the Rest of Us-… | "prnewswire" | "1BD25B85C2DAFCFFD8BDBF4F65666D… | "CCE528" | "AirTran Holdings Inc." | "A Festivus For the Rest of Us-… | "PR Newswire" | 100.0 |
| 2010-12-01 | "https://www.prnewswire.com/new… | "A-Power Reports Third Quarter … | "prnewswire" | "E5FDF9183B63C568FC3FEE4CDE47B2… | "240F7E" | "Collective Brands Inc." | "Collective Brands Reports Thir… | "MarketWire" | 84.95575 |
| 2010-12-01 | "https://www.prnewswire.com/new… | "Addus HomeCare Names Dennis B.… | "prnewswire" | "DCDAD8A79D79B0B0748EF095ADA01C… | "7C790D" | "Addus HomeCare Corp." | "Addus HomeCare Names Dennis B.… | "PR Newswire" | 100.0 |
| 2010-12-01 | "https://www.prnewswire.com/new… | "Aeropostale Names Thomas P. Jo… | "prnewswire" | "3C662748F78229A03322E00B5E3808… | "48D088" | "Aeropostale Inc." | "Aeropostale Names Thomas P. Jo… | "PR Newswire" | 100.0 |
| 2010-12-01 | "https://www.prnewswire.com/new… | "Aeropostale Reports Record Thi… | "prnewswire" | "ECBBEE5FA18E37EB554CFF21FF4654… | "48D088" | "Aeropostale Inc." | "Aeropostale Reports Record Thi… | "PR Newswire" | 100.0 |
Date range#
cw.select(
    pl.col("date").min().alias("earliest"),
    pl.col("date").max().alias("latest"),
).collect()
| earliest | latest |
|---|---|
| date | date |
| 2010-12-01 | 2026-02-28 |
Fuzzy-score distribution#
cw_collected = cw.collect()
print(
    f"fuzzy_score — mean: {cw_collected['fuzzy_score'].mean():.1f},  "
    f"median: {cw_collected['fuzzy_score'].median():.1f},  "
    f"min: {cw_collected['fuzzy_score'].min():.1f},  "
    f"max: {cw_collected['fuzzy_score'].max():.1f}"
)

fig, ax = plt.subplots(figsize=(8, 3))
ax.hist(
    cw_collected["fuzzy_score"].to_list(), bins=40, color="mediumseagreen", alpha=0.8
)
ax.set_xlabel("Fuzzy score")
ax.set_ylabel("Count")
ax.set_title("Newswire–RavenPack crosswalk — fuzzy-score distribution")
fig.tight_layout()
plt.show()
fuzzy_score — mean: 98.5, median: 100.0, min: 80.0, max: 100.0
GDELT vs Scraped Newswires: Different Strengths#
RavenPack’s content is ~95% wire services — Dow Jones Newswires, PR Newswire, Business Wire, and GlobeNewswire. Scraping these wire services directly gives us the same underlying press releases that RavenPack processes, so the per-headline match rate is high.
GDELT crawls the open web — Yahoo Finance, aggregator sites, regional news, blogs. Only ~7% of GDELT’s S&P 500 headlines match RavenPack because they draw from fundamentally different source ecosystems. However, GDELT’s sheer volume (hundreds of thousands of articles per day) compensates: despite the low per-headline match rate, GDELT actually covers a larger fraction of the RavenPack universe than newswire alone.
In short: newswire matches are more precise; GDELT matches are more numerous. Both sources are needed for maximum RavenPack coverage. See notebook 03 (Crosswalk Quality) for the per-source breakdown chart.
Source Comparison#
RavenPack |
GDELT |
Scraped Newswires |
|
|---|---|---|---|
Cost |
Commercial |
Free (BQ scan costs) |
Free |
Entity tagging |
Curated, high quality |
Raw NLP, noisy |
None (via crosswalk) |
Primary sources |
Licensed wire services (~95%) |
Open web (~98%) |
Wire services (same as RP) |
Per-headline RP match rate |
N/A |
~7% (different ecosystems) |
Much higher (same sources) |
RP coverage contribution |
N/A |
Larger (volume compensates) |
Smaller (fewer total headlines) |
ChatGPT upload? |
No (terms of use) |
Yes |
Yes |
Role in pipeline |
Metadata reference |
Largest coverage contributor |
Higher-precision matches |
Bottom Line#
pl.DataFrame(
    {
        "metric": [
            "RP headlines matched",
            "NW headlines matched",
            "Crosswalk pairs",
            "Date range",
        ],
        "value": [
            f"{_rp_match_rate:.1f}% ({_rp_matched_stories:,} / {_rp_total_stories:,})",
            f"{_nw_match_rate:.1f}% ({_nw_matched_urls:,} / {_nw_total_urls:,})",
            f"{len(_cw):,}",
            f"{_cw['date'].min()} to {_cw['date'].max()} ({_cw['date'].n_unique():,} dates)",
        ],
    }
)
| metric | value |
|---|---|
| str | str |
| "RP headlines matched" | "5.0% (843,900 / 16,806,654)" |
| "NW headlines matched" | "24.9% (894,391 / 3,590,391)" |
| "Crosswalk pairs" | "895,043" |
| "Date range" | "2010-12-01 to 2026-02-28 (4,10… |